ReconAgent
In developmentAn agent that reconciles trade confirmation emails against the internal ledger, with offline evaluation and a human review queue.
- 3
- providers: regex, Claude and GPT
Overview
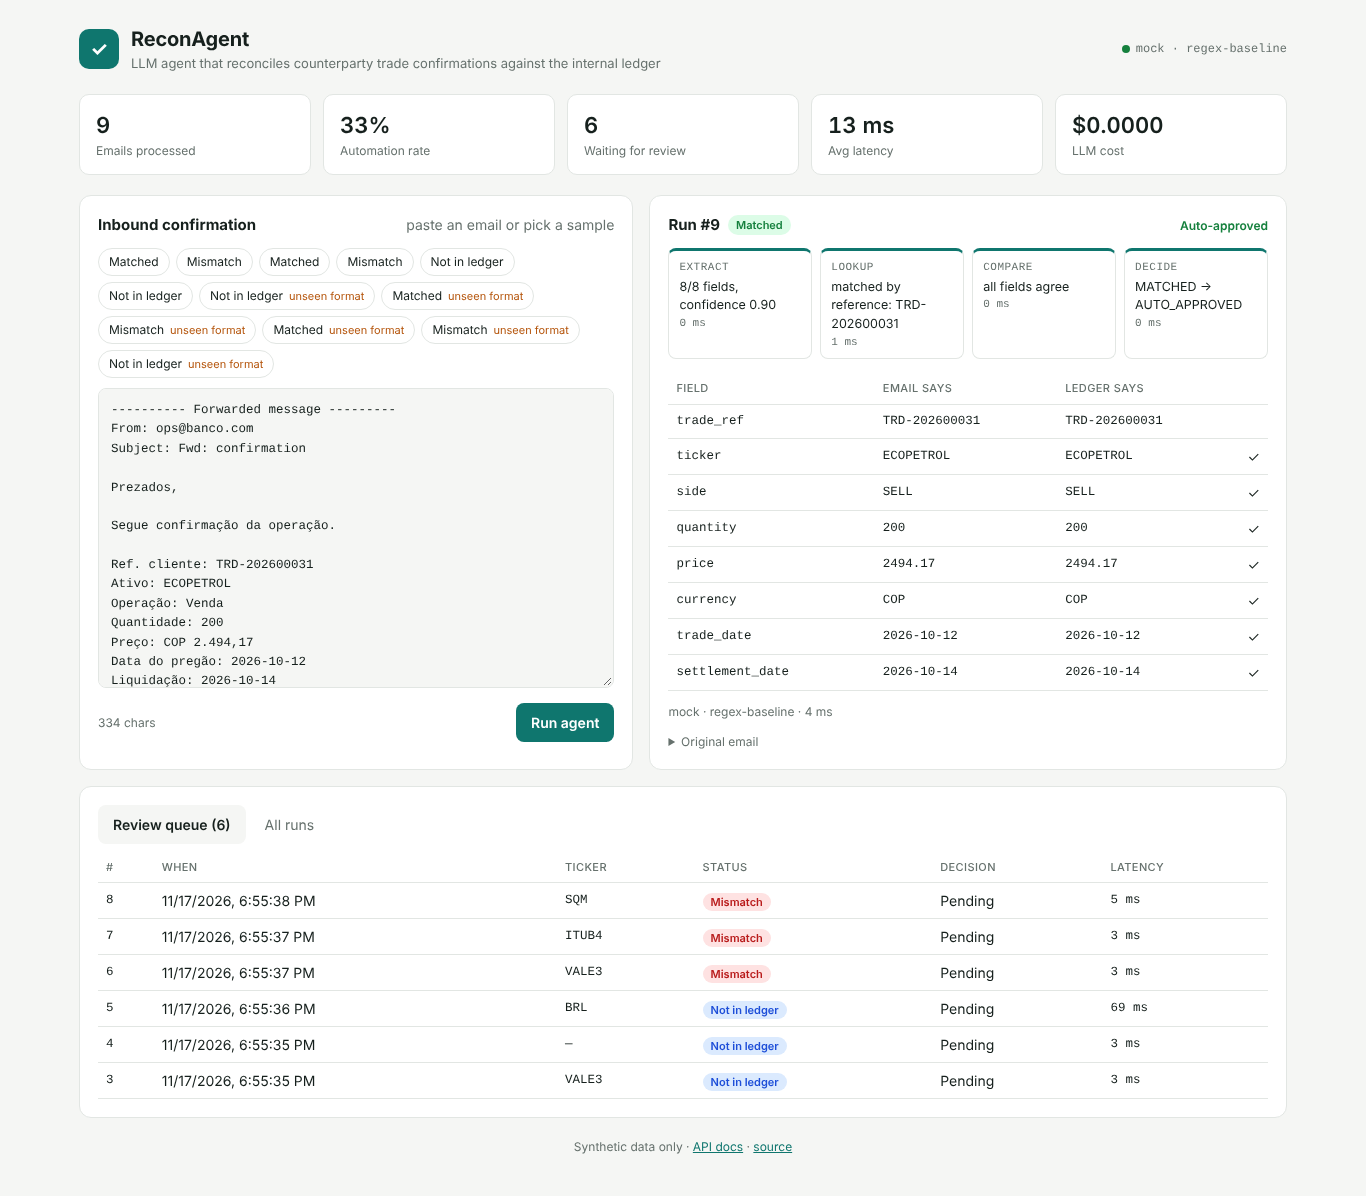
It is a synthetic-data prototype inspired by the email reviewer I built at BTG. An operations desk receives confirmations in three languages and many formats; the agent reads each one, finds the booked trade and decides whether to approve it or send it to an analyst.
The focus is showing how to measure an LLM system: every model or prompt change runs through a set of cases with known answers.
What it does
- A four-step graph
- In LangGraph: extract, look up, compare, decide. Each step records what it did and how long it took.
- Review queue
- Mismatches go to a queue where an analyst approves or rejects with a note, kept in the audit trail.
- Offline evaluation
- Two suites: known formats and never-seen formats (tables, prose with distracting numbers, reply chains).
- Protected demo
- Per-IP limits and a maximum input size, so an exposed LLM key can't run up a bill.
Architecture
Decisions and trade-offs
- Validation outside the model
- The rule checks extracted fields against the system of record. Missing or mismatched values go to review. Evaluation measures whether an incorrect extraction can still pass the rule.
- A no-AI baseline
- Regex extraction gives us a baseline. The evaluation compares coverage on known and unseen formats and measures false approvals.
Quality and operations
- Comparative evaluation and hosted demo are pending publication.
- The prototype includes mocked client tests. Live model runs and the comparison table are pending.
Status and next steps
- Publish the demo and the Claude and GPT evaluation results next to the baseline.
- Read PDF attachments with vision models.
Stack
PythonLangGraphFastAPIPostgreSQLReact + TypeScriptDockerCaddyGitHub Actions